Just came across this article, might give this OS a try some day (not today…).
https://linuxiac.com/vitruvianos-0-3-debuts-as-haiku-inspired-linux-os/
Just came across this article, might give this OS a try some day (not today…).
https://linuxiac.com/vitruvianos-0-3-debuts-as-haiku-inspired-linux-os/
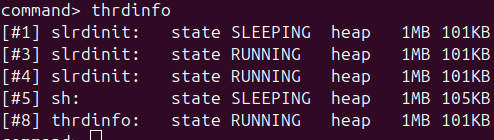
A new thrdinfo program and system call have been added. These are very limited for now but will be improved over time to show CPU usage levels and other things. A graphical version will also be developed later.
Window resizing, moving & closing mostly work properly (including communication of events with client programs). Screenshots still look horrendous with the background not updated properly between interactions, but getting closer to running real apps.
Code produced by GCC uses condensed instructions which may complicate FPU functionality in the kernel, while code produced with my in-house backend has some remaining maths errors. So there are still some small issues to solve.
It’s still a bit of a pain to switch between compilers used to build the OS, and it takes a while to rebuild after most updates (not ideal when trying to see if a small tweak to some maths fixes an issue).
This stuff will be resolved around the 1.2 release, that should be a bit more capable of running arbitrary programs and will have a better build system. For now I will finish some other core pieces needed for the desktop system before trying to run more software on top.
NOTE: The number of epochs in the call to nn_train needs to be increased to show reliable results.
/*
 * Simple Neural Network Library in C
 * Single-file implementation for easy compilation
 *
 * Compile: gcc -Wall -Wextra -std=c99 -O2 -o nn nn.c -lm
 * Run: ./nn
 */

#include <stdio.h>
#include <stdlib.h>
#include <string.h>
#include <math.h>
#include <time.h>

/* ==================== Type Definitions ==================== */

/* Function pointer types for activation functions */
typedef double (*activation_fn)(double x);
typedef double (*activation_deriv_fn)(double x);

/* Layer structure - represents a fully connected layer */
typedef struct {
    int input_size;                    /* Number of inputs to this layer */
    int output_size;                   /* Number of neurons in this layer */
    double *weights;                   /* Weight matrix [output_size][input_size] */
    double *biases;                    /* Bias vector [output_size] */
    double *outputs;                   /* Activated outputs [output_size] */
    double *pre_activation;            /* Pre-activation values [output_size] */
    double *deltas;                    /* Error gradients [output_size] */
    double *weight_grads;              /* Weight gradients [output_size][input_size] */
    double *bias_grads;                /* Bias gradients [output_size] */
    activation_fn activate;            /* Activation function */
    activation_deriv_fn activate_deriv;/* Activation derivative */
} nn_layer_t;

/* Network structure - contains all layers */
typedef struct {
    int num_layers;                    /* Number of layers (excluding input) */
    nn_layer_t **layers;               /* Array of layer pointers */
    double learning_rate;              /* Learning rate for SGD */
    double **layer_inputs;             /* Store inputs for each layer */
} nn_network_t;

/* ==================== Activation Functions ==================== */

/* Sigmoid activation: 1 / (1 + e^-x) */
static double nn_sigmoid(double x) {
    return 1.0 / (1.0 + exp(-x));
}

/* Sigmoid derivative: sigmoid(x) * (1 - sigmoid(x)) */
static double nn_sigmoid_deriv(double x) {
    double s = nn_sigmoid(x);
    return s * (1.0 - s);
}

/* ReLU activation: max(0, x) */
static double nn_relu(double x) {
    return x > 0.0 ? x : 0.0;
}

/* ReLU derivative: 1 if x > 0, else 0 */
static double nn_relu_deriv(double x) {
    return x > 0.0 ? 1.0 : 0.0;
}

/* Tanh activation */
static double nn_tanh(double x) {
    return tanh(x);
}

/* Tanh derivative: 1 - tanh(x)^2 */
static double nn_tanh_deriv(double x) {
    double t = tanh(x);
    return 1.0 - t * t;
}

/* Linear activation (identity) */
static double nn_linear(double x) {
    return x;
}

/* Linear derivative (always 1) */
static double nn_linear_deriv(double x) {
    (void)x;  /* Unused parameter */
    return 1.0;
}

/* ==================== Layer Functions ==================== */

/* Create a new layer with specified dimensions */
static nn_layer_t* nn_create_layer(int input_size, int output_size,
                                   activation_fn activate,
                                   activation_deriv_fn activate_deriv) {
    nn_layer_t *layer = (nn_layer_t*)malloc(sizeof(nn_layer_t));
    if (!layer) {
        fprintf(stderr, "Error: Failed to allocate layer\n");
        exit(EXIT_FAILURE);
    }

    layer->input_size = input_size;
    layer->output_size = output_size;

    /* Allocate weight matrix: output_size rows, input_size columns */
    layer->weights = (double*)malloc(output_size * input_size * sizeof(double));
    layer->biases = (double*)malloc(output_size * sizeof(double));
    layer->outputs = (double*)malloc(output_size * sizeof(double));
    layer->pre_activation = (double*)malloc(output_size * sizeof(double));
    layer->deltas = (double*)malloc(output_size * sizeof(double));
    layer->weight_grads = (double*)malloc(output_size * input_size * sizeof(double));
    layer->bias_grads = (double*)malloc(output_size * sizeof(double));
    layer->activate = activate;
    layer->activate_deriv = activate_deriv;

    /* Check all allocations succeeded */
    if (!layer->weights || !layer->biases || !layer->outputs ||
        !layer->pre_activation || !layer->deltas ||
        !layer->weight_grads || !layer->bias_grads) {
        fprintf(stderr, "Error: Failed to allocate layer arrays\n");
        exit(EXIT_FAILURE);
    }

    return layer;
}

/* Free a layer and all its memory */
static void nn_free_layer(nn_layer_t *layer) {
    if (!layer) return;
    free(layer->weights);
    free(layer->biases);
    free(layer->outputs);
    free(layer->pre_activation);
    free(layer->deltas);
    free(layer->weight_grads);
    free(layer->bias_grads);
    free(layer);
}

/* Initialize layer weights with small random values */
static void nn_init_layer_weights(nn_layer_t *layer, unsigned int seed) {
    srand(seed);

    /* Xavier initialization scaled for sigmoid */
    double scale = sqrt(6.0 / (layer->input_size + layer->output_size));

    for (int i = 0; i < layer->output_size * layer->input_size; i++) {
        layer->weights[i] = ((double)rand() / RAND_MAX - 0.5) * 2.0 * scale;
        layer->weight_grads[i] = 0.0;
    }

    for (int i = 0; i < layer->output_size; i++) {
        layer->biases[i] = 0.0;
        layer->bias_grads[i] = 0.0;
    }
}

/* ==================== Network Functions ==================== */

/* Create a neural network with specified layer sizes */
nn_network_t* nn_create_network(const int *layer_sizes, int num_layers,
                                double learning_rate) {
    if (num_layers < 2) {
        fprintf(stderr, "Error: Network needs at least 2 layers (input + output)\n");
        return NULL;
    }

    nn_network_t *net = (nn_network_t*)malloc(sizeof(nn_network_t));
    if (!net) {
        fprintf(stderr, "Error: Failed to allocate network\n");
        return NULL;
    }

    /* num_layers - 1 because first layer is input layer (no computation) */
    net->num_layers = num_layers - 1;
    net->learning_rate = learning_rate;

    net->layers = (nn_layer_t**)malloc(net->num_layers * sizeof(nn_layer_t*));
    net->layer_inputs = (double**)malloc(net->num_layers * sizeof(double*));

    if (!net->layers || !net->layer_inputs) {
        fprintf(stderr, "Error: Failed to allocate network arrays\n");
        free(net);
        return NULL;
    }

    /* Create each layer */
    for (int i = 0; i < net->num_layers; i++) {
        net->layers[i] = nn_create_layer(layer_sizes[i], layer_sizes[i + 1],
                                         nn_sigmoid, nn_sigmoid_deriv);
        net->layer_inputs[i] = (double*)malloc(layer_sizes[i] * sizeof(double));

        if (!net->layer_inputs[i]) {
            fprintf(stderr, "Error: Failed to allocate layer inputs\n");
            exit(EXIT_FAILURE);
        }
    }

    return net;
}

/* Free network and all its layers */
void nn_free_network(nn_network_t *net) {
    if (!net) return;

    for (int i = 0; i < net->num_layers; i++) {
        nn_free_layer(net->layers[i]);
        free(net->layer_inputs[i]);
    }

    free(net->layers);
    free(net->layer_inputs);
    free(net);
}

/* Initialize all network weights */
void nn_init_weights(nn_network_t *net, unsigned int seed) {
    for (int i = 0; i < net->num_layers; i++) {
        nn_init_layer_weights(net->layers[i], seed + i);
    }
}

/* Set activation function for all layers */
void nn_set_activation(nn_network_t *net, activation_fn activate,
                       activation_deriv_fn activate_deriv) {
    for (int i = 0; i < net->num_layers; i++) {
        net->layers[i]->activate = activate;
        net->layers[i]->activate_deriv = activate_deriv;
    }
}

/* Set activation function for specific layer */
void nn_set_layer_activation(nn_network_t *net, int layer_idx,
                             activation_fn activate,
                             activation_deriv_fn activate_deriv) {
    if (layer_idx < 0 || layer_idx >= net->num_layers) {
        fprintf(stderr, "Error: Invalid layer index %d\n", layer_idx);
        return;
    }
    net->layers[layer_idx]->activate = activate;
    net->layers[layer_idx]->activate_deriv = activate_deriv;
}

/* ==================== Forward Pass ==================== */

/* Perform forward propagation through the network */
double* nn_forward(nn_network_t *net, const double *input) {
    double *current_input = (double*)input;

    for (int i = 0; i < net->num_layers; i++) {
        nn_layer_t *layer = net->layers[i];

        /* Store input for backpropagation */
        memcpy(net->layer_inputs[i], current_input,
               layer->input_size * sizeof(double));

        /* Compute weighted sum + bias for each neuron */
        for (int j = 0; j < layer->output_size; j++) {
            double sum = layer->biases[j];

            for (int k = 0; k < layer->input_size; k++) {
                sum += layer->weights[j * layer->input_size + k] * current_input[k];
            }

            layer->pre_activation[j] = sum;
            layer->outputs[j] = layer->activate(sum);
        }

        /* Output becomes input for next layer */
        current_input = layer->outputs;
    }

    return current_input;
}

/* ==================== Backward Pass ==================== */

/* Perform backpropagation to compute gradients */
void nn_backward(nn_network_t *net, const double *target) {
    nn_layer_t *last_layer = net->layers[net->num_layers - 1];

    /* Output layer: compute error directly from target */
    for (int i = 0; i < last_layer->output_size; i++) {
        double error = last_layer->outputs[i] - target[i];
        last_layer->deltas[i] = error * last_layer->activate_deriv(last_layer->pre_activation[i]);
    }

    /* Hidden layers: propagate error backwards */
    for (int i = net->num_layers - 2; i >= 0; i--) {
        nn_layer_t *layer = net->layers[i];
        nn_layer_t *next_layer = net->layers[i + 1];

        for (int j = 0; j < layer->output_size; j++) {
            double error = 0.0;

            /* Sum weighted deltas from next layer */
            for (int k = 0; k < next_layer->output_size; k++) {
                error += next_layer->deltas[k] * next_layer->weights[k * next_layer->input_size + j];
            }

            layer->deltas[j] = error * layer->activate_deriv(layer->pre_activation[j]);
        }
    }

    /* Accumulate gradients for all layers */
    for (int i = 0; i < net->num_layers; i++) {
        nn_layer_t *layer = net->layers[i];
        double *inputs = net->layer_inputs[i];

        for (int j = 0; j < layer->output_size; j++) {
            layer->bias_grads[j] += layer->deltas[j];

            for (int k = 0; k < layer->input_size; k++) {
                layer->weight_grads[j * layer->input_size + k] +=
                    layer->deltas[j] * inputs[k];
            }
        }
    }
}

/* Update weights using accumulated gradients */
static void nn_update_weights(nn_network_t *net, int batch_size) {
    double lr = net->learning_rate / batch_size;

    for (int i = 0; i < net->num_layers; i++) {
        nn_layer_t *layer = net->layers[i];

        for (int j = 0; j < layer->output_size * layer->input_size; j++) {
            layer->weights[j] -= lr * layer->weight_grads[j];
            layer->weight_grads[j] = 0.0;
        }

        for (int j = 0; j < layer->output_size; j++) {
            layer->biases[j] -= lr * layer->bias_grads[j];
            layer->bias_grads[j] = 0.0;
        }
    }
}

/* ==================== Training ==================== */

/* Compute Mean Squared Error loss */
double nn_mse_loss(const double *predicted, const double *target, int size) {
    double sum = 0.0;
    for (int i = 0; i < size; i++) {
        double diff = predicted[i] - target[i];
        sum += diff * diff;
    }
    return sum / size;
}

/* Train the network on a dataset */
void nn_train(nn_network_t *net, double **inputs, double **targets,
              int num_samples, int epochs, int verbose) {
    int output_size = net->layers[net->num_layers - 1]->output_size;

    for (int epoch = 0; epoch < epochs; epoch++) {
        double total_loss = 0.0;

        /* Forward and backward pass for each sample */
        for (int s = 0; s < num_samples; s++) {
            nn_forward(net, inputs[s]);
            nn_backward(net, targets[s]);

            double *output = net->layers[net->num_layers - 1]->outputs;
            total_loss += nn_mse_loss(output, targets[s], output_size);
        }

        /* Update weights after processing all samples */
        nn_update_weights(net, num_samples);

        /* Print progress */
        if (verbose && (epoch + 1) % 100 == 0) {
            printf("Epoch %5d, Loss: %.6f\n", epoch + 1, total_loss / num_samples);
        }
    }
}

/* Get prediction for a single input */
double* nn_predict(nn_network_t *net, const double *input) {
    return nn_forward(net, input);
}

/* ==================== Utility Functions ==================== */

/* Print network architecture */
void nn_print_architecture(nn_network_t *net) {
    printf("Network Architecture:\n");
    printf("  Layers: %d\n", net->num_layers + 1);
    printf("  Learning Rate: %.4f\n", net->learning_rate);
    printf("  Structure: ");

    for (int i = 0; i < net->num_layers; i++) {
        printf("%d", net->layers[i]->input_size);
        if (i < net->num_layers - 1) {
            printf(" -> ");
        }
    }
    printf(" -> %d\n", net->layers[net->num_layers - 1]->output_size);
}

/* Print network outputs for debugging */
void nn_print_outputs(nn_network_t *net) {
    printf("Layer Outputs:\n");
    for (int i = 0; i < net->num_layers; i++) {
        nn_layer_t *layer = net->layers[i];
        printf("  Layer %d: [", i);
        for (int j = 0; j < layer->output_size; j++) {
            printf("%.4f", layer->outputs[j]);
            if (j < layer->output_size - 1) printf(", ");
        }
        printf("]\n");
    }
}

/* ==================== Example: XOR Problem ==================== */

int main(void) {
    printf("=== Simple Neural Network Library Demo ===\n\n");

    /* Define network architecture: 2 inputs, 4 hidden, 1 output */
    int layer_sizes[] = {2, 4, 1};
    int num_layers = sizeof(layer_sizes) / sizeof(layer_sizes[0]);

    /* Create network with learning rate 0.1 */
    nn_network_t *net = nn_create_network(layer_sizes, num_layers, 0.1);

    if (!net) {
        fprintf(stderr, "Failed to create network\n");
        return EXIT_FAILURE;
    }

    nn_print_architecture(net);
    printf("\n");

    /* Initialize weights with seed for reproducibility */
    nn_init_weights(net, 42);

    /* XOR training data */
    double inputs[4][2] = {
        {0.0, 0.0},
        {0.0, 1.0},
        {1.0, 0.0},
        {1.0, 1.0}
    };

    double targets[4][1] = {
        {0.0},
        {1.0},
        {1.0},
        {0.0}
    };

    /* Create arrays of pointers for training function */
    double *input_ptrs[4];
    double *target_ptrs[4];

    for (int i = 0; i < 4; i++) {
        input_ptrs[i] = inputs[i];
        target_ptrs[i] = targets[i];
    }

    /* Train the network */
    printf("Training on XOR problem (1000 epochs)...\n\n");
    nn_train(net, input_ptrs, target_ptrs, 4, 1000, 1);

    /* Test the trained network */
    printf("\n=== Test Results ===\n");
    printf("Input          -> Output (Target)\n");
    printf("-----------------------------------\n");

    for (int i = 0; i < 4; i++) {
        double *output = nn_predict(net, inputs[i]);
        printf("[%.1f, %.1f] -> %.4f (%.1f)\n",
               inputs[i][0], inputs[i][1], output[0], targets[i][0]);
    }

    /* Calculate final accuracy */
    printf("\n=== Final Metrics ===\n");
    double final_loss = 0.0;
    int correct = 0;

    for (int i = 0; i < 4; i++) {
        double *output = nn_predict(net, inputs[i]);
        final_loss += nn_mse_loss(output, targets[i], 1);

        /* Check if prediction matches target (threshold 0.5) */
        double predicted_class = output[0] > 0.5 ? 1.0 : 0.0;
        if (predicted_class == targets[i][0]) {
            correct++;
        }
    }

    printf("Final MSE Loss: %.6f\n", final_loss / 4.0);
    printf("Accuracy: %d/4 (%.1f%%)\n", correct, (correct / 4.0) * 100.0);

    /* Clean up */
    nn_free_network(net);

    printf("\n=== Demo Complete ===\n");
    return EXIT_SUCCESS;
}
I got a little bored after a couple of days of GUI work so I decided to try something different and re-run an AI experiment I tried a year or so ago. The goal of this experiement is to use an AI to design a starting point of a new AI system in the form of a small neural network library.
This time it still didn’t work on the first try, but the version it gave when I asked it to correct & simplify the code actually seems sorta okay-ish. It works for me as long as the number of epochs in the call to nn_train is increased to around 10,000 or higher. So it works, probably not as efficiently or reliably as the best neural network code, but maybe well enough for a starting point of a mini AI framework. UPDATE: The code of the working version has been uploaded as a second post (the post immediately after this one).
Side note: I used to be a small-time investor in the company behind Qwen (Alibaba, maybe better known for online retail) but I don’t currently hold any shares in it.
The main advantage of my OS is it’s unique combination of features:
These will further be compounded by future/in-development extensions:
It’s not in my interests to make myself look like anyone’s slave in the way that other people feel the need to prove that they’re “hard workers”, I’ve always had to rely on my programming abilities for my self confidence instead.
It’s in my interests to inform people that this work such as programming for new hardware has always been very easy for me – much easier than it is for the various western government bodies or for Elon Musk and the AI companies – and I could’ve already destroyed any competitor with ten thousand precision drones if I wanted to destroy people’s lives the way others do.
The GUI system will be finished relatively slowly (after initial work is complete it will take some time to get it working as smoothly as other platforms) but more complex screenshots will follow in the next few days or so.
Initial, limited, versions of file managers, terminal emulators, text editors etc. should be easy to get going on the desktop system over the next month or so but these will also need a lot of updates to become fully operational.
I plan to gradually add more advanced documentation to the system, this will include additional materials like legacy encyclopaedia & dictionary content as well as technical documentation for the system.
Initial releases were just bootable prototypes mostly showing a few kernel features, later releases will have proper versioning and will eventually allow some updates to be installed from within the platform.
Most basic operating system features are now working, so aside from gradually expanding those features with new capabilities and new hardware drivers the most important updates will just be refining & hardening the existing system: